Use case · batch processing
Batch jobs and data pipelines for a fraction of the cost.
Dataset generation, transcription backlogs, image processing, financial simulation: work that can be split into thousands of containers and retried on failure is what SaladCloud does best, at up to 90% less than hyperscaler batch services.
$1,260to transcribe 1,000,000 hours with Parakeet TDT 1.1B
$5,110to transcribe 1,000,000 hours with Whisper Large v3
16,000+daily active GPUs to fan out across
0cold-start charges or minimum commitments
How batch runs on Salad
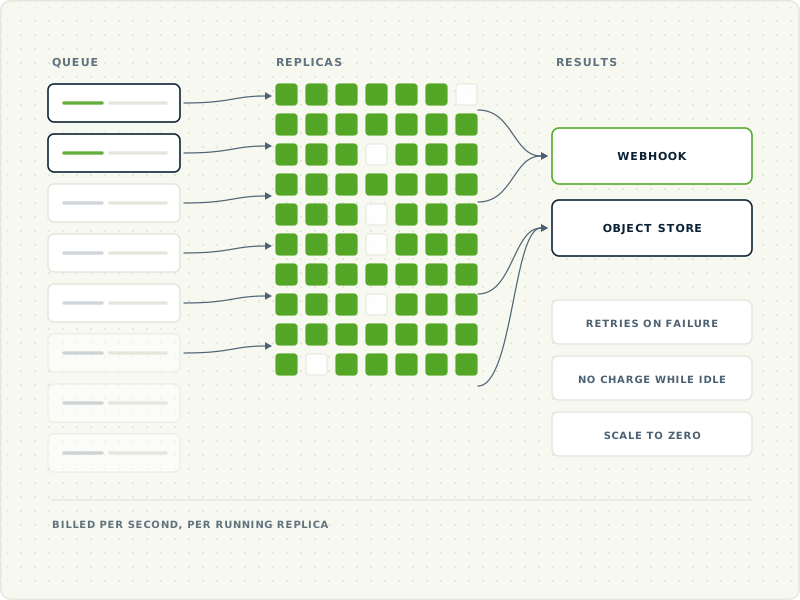
Queue in, results out, replicas in between.
Enqueue work
Push jobs to Salad Job Queues, or run your own with RabbitMQ, SQS, or the open-source Kelpie API for long-running tasks.
Fan out
Scale a container group to hundreds or thousands of replicas at Lowest priority for the lowest-cost GPU-hour. SCE keeps the replica count filled as nodes churn.
Collect results
Webhook callbacks and checkpointing to object storage make interruption a non-event. Failed jobs are retried; you pay only for running seconds.
Benchmarks
Massive jobs, small invoices.
Bring the backlog.
Committed contracts and volume pricing for recurring pipelines.